Data Modernization in Banking: Bridging Legacy Cores to the Cloud Data Warehouse
Data modernization in banking moves legacy core data into a cloud warehouse you can trust. How to extract, convert, load and reconcile it, step by step.
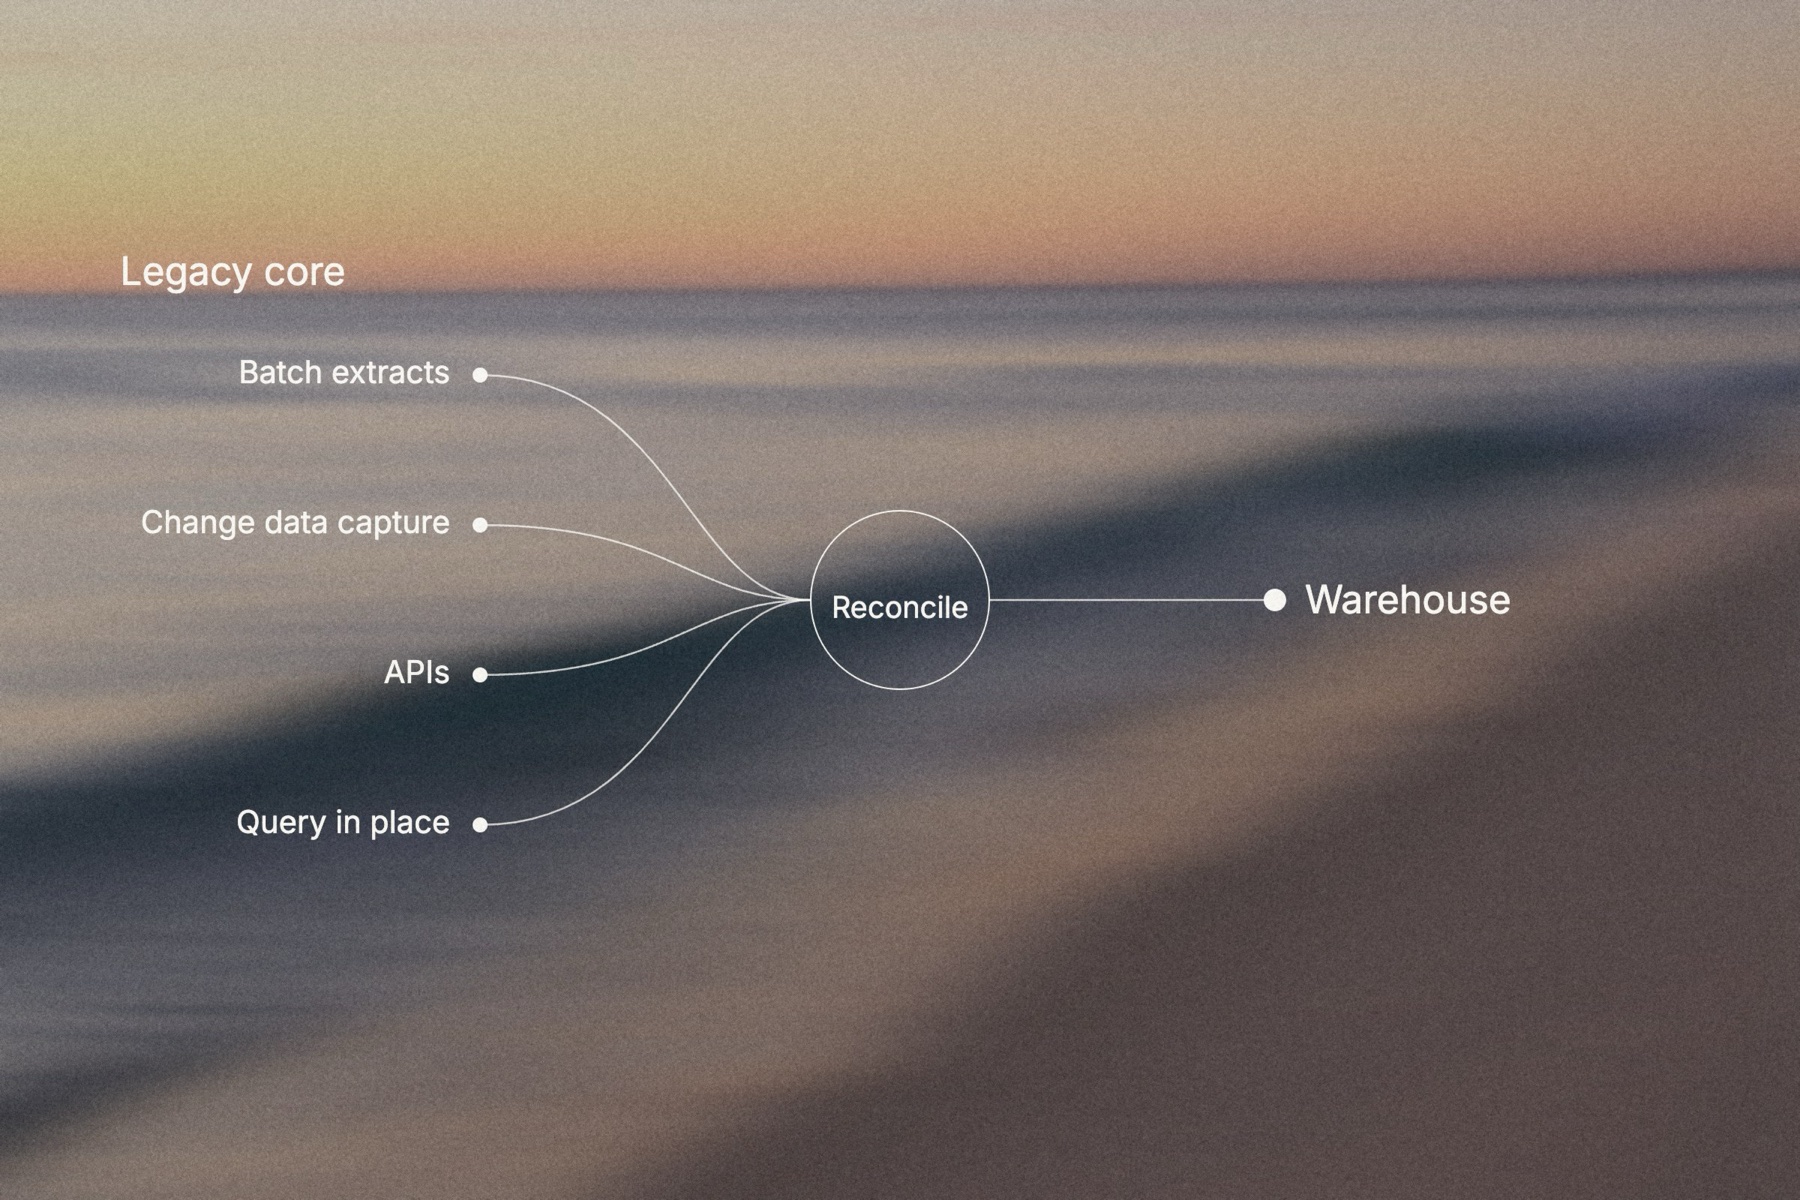
Data modernization in banking means making the data held in legacy core systems available, accurate and traceable in modern platforms, usually a cloud data warehouse, without disrupting the core that posts transactions every day. In practice it has four parts: getting data out of the core and the systems around it, converting old formats, loading it on a reliable schedule, and proving that every number in the warehouse matches its source.
The core itself often stays where it is. Many banks and credit unions modernize the data first and replace the core later, or never, so the warehouse has to live alongside an IBM i (AS/400), a mainframe or a vendor-hosted core for years.
Where engini fits: engini does not replicate your whole core into a warehouse; replication and change data capture tools do that. engini reaches the systems around it, including IBM DB2, SQL Server and Oracle databases and file drops behind your firewall through its on-prem agent, so you can automate the feeds, reconciliation checks and exception handling that keep the warehouse trustworthy, and give AI agents scoped access to the data where it lives. Start with the engini docs index.
Key Takeaways
- Data modernization in banking is mostly about trust: the warehouse is only useful if its balances and counts match the core every day.
- Legacy core data needs conversion: IBM i stores character fields in EBCDIC and numbers in packed-decimal format, which modern tools must decode correctly.
- There are four ways to move core data: batch extract files, change data capture from database journals, APIs or events, and querying in place.
- Reconcile every load at several levels (record counts, balances, general ledger totals) and keep the results as evidence of lineage.
- Regulators have asked banks to improve risk data aggregation since the Basel Committee's BCBS 239 principles in January 2013.
What is data modernization in banking?
Data modernization in banking is the work of moving a bank's data from systems designed for transaction processing into platforms designed for reporting, analytics and AI, while keeping it complete, consistent and traceable. It is not the same as a core conversion, which replaces the system of record; for that, see core banking migration.
A modernized data estate usually has five layers:
Most of the effort goes into the movement and control layers. Storage is the easiest part to buy; trust in what is stored takes the most work.
Why is legacy core data hard to move?
Legacy core data is hard to move because it is stored in formats and structures that predate modern data tools, and because the core is busy posting transactions and cannot be slowed down by extraction. Three technical issues come up on IBM i, the platform behind many older banking cores.
- Character encoding. IBM documents that a character field of type A "normally" contains EBCDIC data unless a CCSID keyword says otherwise (IBM i documentation). A pipeline that reads the field with the wrong code page produces text that looks valid but is wrong, which is dangerous for names, addresses and account identifiers.
- Packed-decimal numbers. In packed-decimal format, each byte except the last holds two decimal digits, and the last byte holds one digit and the sign, with hexadecimal F for positive and D for negative (IBM i documentation). Balances and amounts are often stored this way, and a generic parser can turn them into wrong numbers without raising an error.
- Record layouts kept in programs. In older applications, the layout of a record is sometimes defined in the program that writes it rather than in the database. When the program changes, the layout changes, and any extraction built on the old layout reads fields at the wrong positions.
Note: The common thread is silent failure. Each of these problems can load wrong values that pass basic type checks, which is why reconciliation, not schema validation, is the real test.
How do banks move core data into a cloud data warehouse?
Banks move core data with one of four methods, and most use more than one, chosen per source. The right choice depends on how fresh the data must be, how much load the core can take, and what the core vendor supports.
On IBM i, change data capture builds on journaling. IBM's documentation explains that the system writes entries for changes to an object called a journal receiver, and that entries for changes to database records can include the entire image of the record (IBM i: How journal management works). Replication tools read those entries instead of querying the tables, which keeps the extra load on the core low.
On the warehouse side, loading can also be continuous. Snowflake's documentation describes Snowpipe as continuously loading data from files as they arrive in a stage, with new data typically available for queries within minutes; Snowflake also states that it does not guarantee load latency (Snowflake: Introduction to Snowpipe). Other warehouses offer similar streaming and file-loading options; check your platform's own documentation for its limits.
Tip: Choose the method per source, not per project. A loan origination system that only exports files and a core that supports journaling do not need the same pipeline.
How do you prove the warehouse data is right?
You prove warehouse data is right by reconciling every load against its source, at several levels, and keeping the results. A load that completed without errors is not evidence that the data is correct.
The same idea sits behind supervisory expectations for risk data. The Basel Committee published its Principles for effective risk data aggregation and risk reporting, known as BCBS 239, on 9 January 2013, after the financial crisis showed that many banks were unable to aggregate risk exposures and identify concentrations fully, quickly and accurately (BIS: BCBS 239). A warehouse that is reconciled daily, with the results kept, is a large part of the answer to those principles.
A practical sequence for data modernization in banking
A practical sequence starts with one use case and its reconciliation, not with moving every table. Each step below builds on a dataset you can already prove.
- Inventory the sources. List the core, the systems around it, and every file or extract they already produce, with owners and schedules.
- Pick the first use case. A regulatory report, a risk dataset or a finance report that is rebuilt by hand today is a good start, because the manual version gives you a baseline to compare.
- Write the reconciliation first. Define the counts, balances and totals that must match before any data moves.
- Choose the method per source. Files, change data capture, APIs or querying in place, using the table above.
- Decode and load. Convert EBCDIC and packed-decimal fields with tested mappings, and keep the mapping under version control.
- Reconcile every run and keep the evidence. Store each result with its date, source and differences, so lineage can be shown later.
- Retire the side copies. Once the warehouse version reconciles, switch reports to it and stop the spreadsheets and one-off extracts it replaces.
- Open the data to AI agents carefully. Give agents read access through governed connections, limited to the tools and data they need.
For the wider migration checklist, see banking data migration best practices; for how agents reach legacy systems, see MCP for finance systems and legacy cores.
How engini helps with data modernization in banking
engini handles the cross-system work around the warehouse: moving specific feeds, running reconciliation checks, tracking exceptions and giving AI agents controlled access to source systems. It is not a bulk replication or change data capture tool.
- Reach the core's databases behind your firewall. The on-prem agent runs on your own server and opens every connection outbound, so you open no inbound ports. It reaches on-premises databases (SQL Server, Oracle, IBM DB2, MySQL, PostgreSQL and ODBC sources), file drops in local folders and network shares, and internal applications. IBM AS/400 systems, the classic core in many older financial institutions, are reached this way.
- Run your own SQL on DB2. The IBM DB2 integration creates, reads and updates records, in batches too, and runs your own SQL statements and existing stored procedures. For a cloud connection, you set the database's CCSID on the connection, so character data is read with the right encoding.
- Work with the warehouse. The Snowflake integration runs custom SQL, creates and updates rows, and can start a workflow on a new row, an updated row or a scheduled query. That makes it possible to run the same reconciliation query on the core and the warehouse every day and compare the results.
- Move files that already exist. Workflows read and write file drops on your own servers and over SFTP, so transaction files, clearing reports and payment instructions can be checked and delivered to the local financial system or to the warehouse's landing area.
- Track differences in a table. Each reconciliation difference can be written to an engini Table, and a table automation can start a workflow when a record is created or updated, for example to alert the data owner.
- Give AI agents scoped, logged access. An AI agent step in a workflow, or an agent you build with the SDK or MCP, can read source data in place to explain a difference. A toolset limits an agent to the tools and the connection it should use, and engini acts as the connected account, so a read-only database account keeps the agent read-only.
- See every run. Run history records each execution, notifications email you when a workflow fails, and the audit log can be exported and streamed to your SIEM.
- Controls. Single sign-on, roles including custom roles, and separate development, staging and production environments. engini holds SOC 2 Type II and ISO 27001; details are on the security page. See how engini supports financial services.
When you do not need engini: to replicate a whole core continuously into a warehouse, use a change data capture or replication tool, or your core vendor's extracts. If your warehouse is already fed, reconciled and monitored by your data platform, and no systems behind your firewall need new feeds, you may not need another platform.
Frequently Asked Questions
What is data modernization in banking?
Data modernization in banking makes legacy core data available, accurate and traceable in modern platforms such as a cloud data warehouse. It covers extracting data from the core and nearby systems, converting old formats, loading it reliably, and reconciling it against the source.
Do banks have to replace the core to modernize their data?
No, many banks modernize their data while keeping the current core. Data is extracted or replicated from the core into a warehouse, and the core is replaced later, or not at all.
Why is AS/400 data hard to load into a cloud warehouse?
Because IBM i stores character fields in EBCDIC and many numbers in packed-decimal format. Both must be decoded correctly, and some record layouts are defined in programs rather than in the database, so a wrong mapping can load wrong values without an error.
What is change data capture on IBM i?
Change data capture on IBM i reads the database journal, where the system records changes to journaled files, and replicates each insert, update and delete. Because it reads journal entries instead of querying tables, it adds little load to the core.
How do you know a banking data warehouse matches the core?
You reconcile every load: record counts, balances, general ledger totals, field samples and freshness, compared between the source and the warehouse. Keep each result, so you can show lineage when auditors or examiners ask.
Sources
- IBM i documentation: Unicode considerations for database files, data type
- IBM i documentation: Packed-decimal format
- IBM i documentation: How journal management works
- Snowflake documentation: Introduction to Snowpipe
- Bank for International Settlements: Principles for effective risk data aggregation and risk reporting (BCBS 239)
- engini docs: On Prem Agent, IBM DB2 and Snowflake
- engini docs: On Prem Files, Table Automations and Workflow Run History