Core Migration Checklist for Banks and Credit Unions: Ledger, Data and Cutover Without Rewriting Legacy Code
A core migration checklist for banks and credit unions: contracts, data mapping, five validation layers, rehearsals, cutover and integrations.
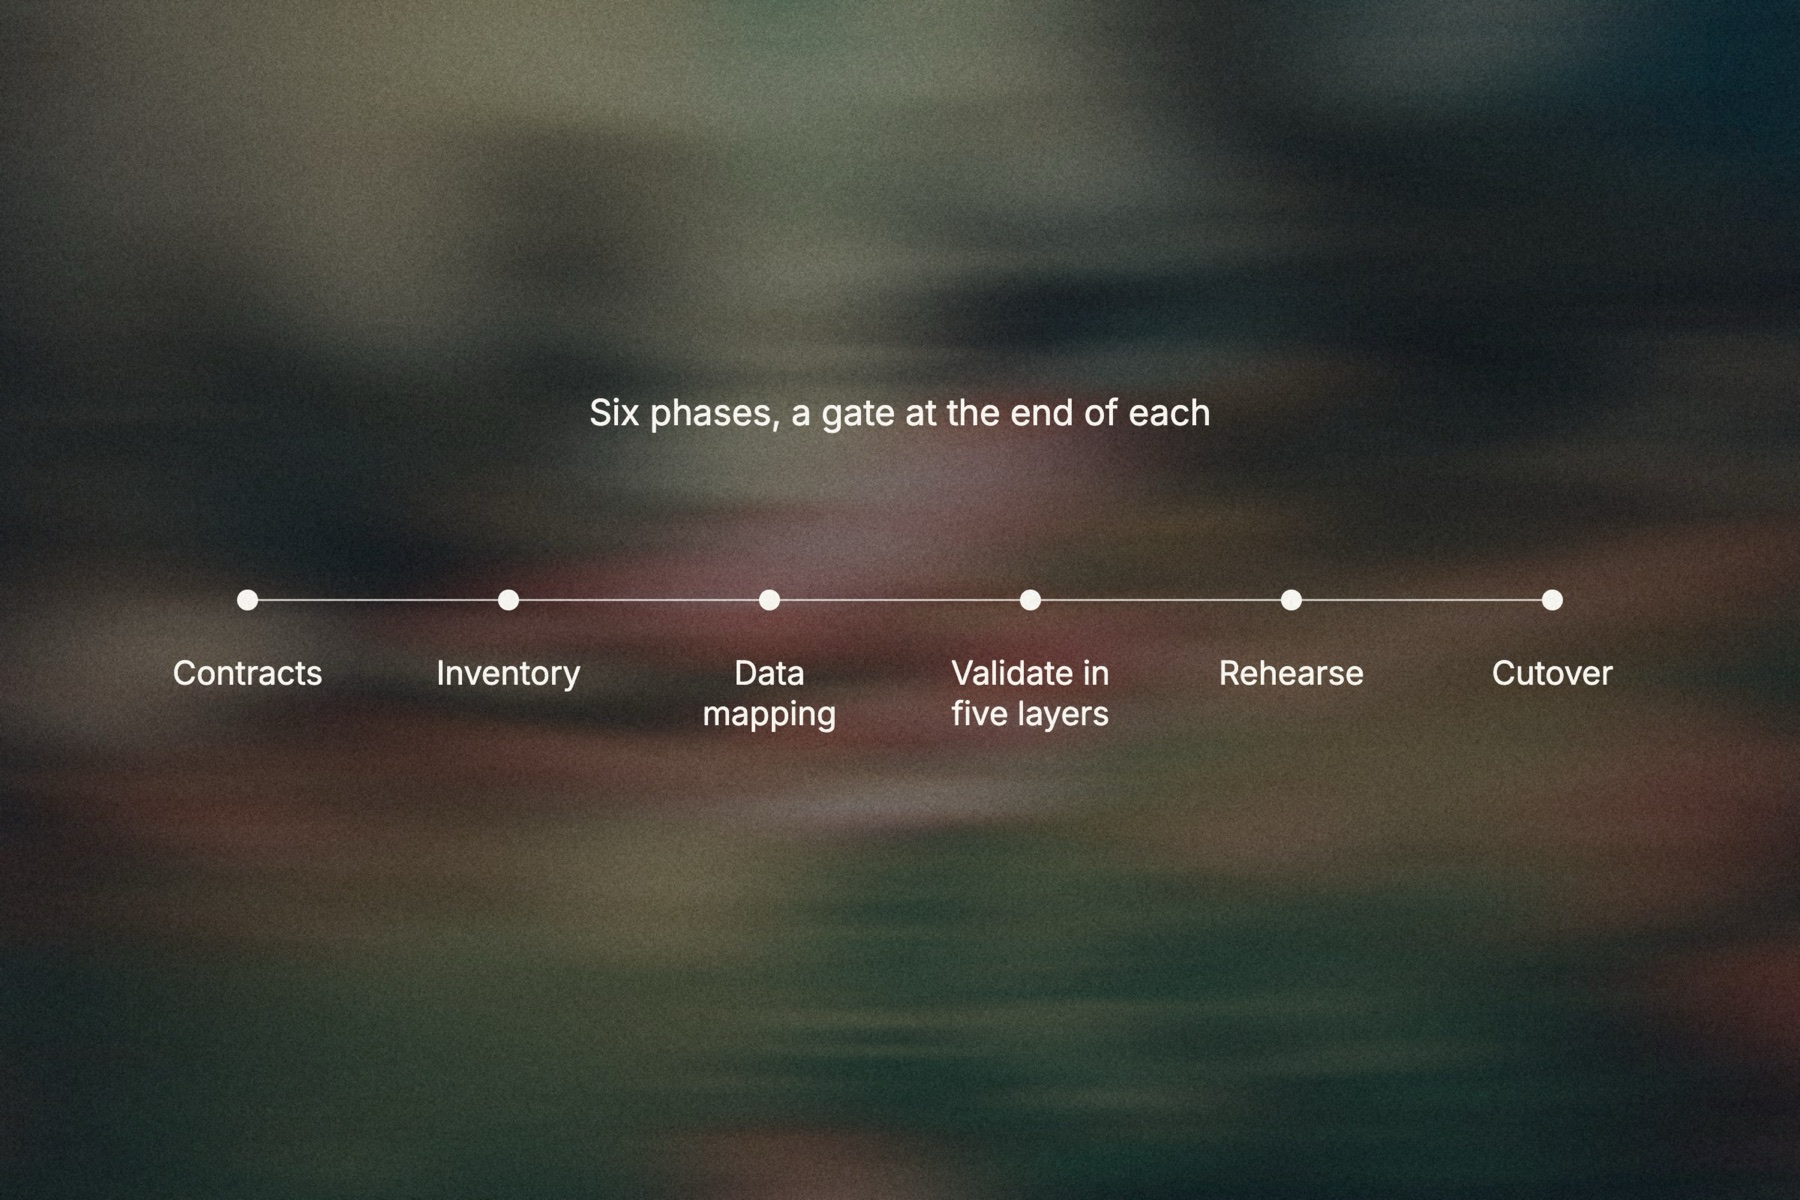
A core migration checklist for banks and credit unions covers six areas: the contracts with the old and new core providers, the data and its mapping, validation before cutover, rehearsals, the cutover weekend itself, and every system that connects to the core. The data and those connections are where most of the work, and most of the risk, sit.
The checklist below is written for a community bank or credit union moving its ledger, deposits and loans to a new core, whether hosted by a core provider or run on its own servers. It assumes you keep the legacy code as it is and move the data, rather than rewriting the old system before you leave it.
Where engini fits: engini does not convert a core; your new core provider's conversion team does that. engini handles the systems around the core: it reads the old and new cores' databases and files (on premises, through the on-prem agent), runs balancing checks between them, writes every difference to a table with an owner, and moves each integration that touched the old core to the new one. See the on-prem agent docs.
Key Takeaways
- Start the checklist with contracts: the deconversion terms in your current core contract decide what data you get, in what format, and when.
- Inventory every system that reads from or writes to the core before mapping starts: lending, cards, online banking, the general ledger, compliance tools, reports and file feeds.
- Validate in five layers before cutover: structure, referential integrity, business rules, financial balancing, and regulatory record completeness.
- Run at least two full mock conversions on production-sized data, and time every cutover step against the window you have.
- Credit unions report a planned core application conversion on NCUA's Credit Union Profile form when it is expected within the next 24 months.
- Keep identity records available after conversion: the CIP rule requires banks to keep identifying information for five years after an account closes.
What should a core migration checklist include?
A core migration checklist should include every decision and check that has to be done before the new core can run the institution on Monday morning. Group it by phase, with an owner and a date for each item.
The rest of this guide goes through each phase as a checklist.
Phase 1: governance and contracts
Governance and contracts come first because they decide your timeline and what data you will receive.
- Board and management sign-off on the project, the budget and the decision criteria for go or no-go.
- Deconversion terms with the current provider: what files they deliver, in what format, how many test extracts, at what cost, and on what notice period.
- Conversion terms with the new provider: how many mock conversions are included, who maps the data, who balances, and what happens if a date slips.
- Third-party risk management: the new core provider and any conversion consultant are third-party relationships. The June 2023 interagency guidance on third-party relationships from the Federal Reserve, the FDIC and the OCC describes risk management principles for each stage of the relationship life cycle (OCC Bulletin 2023-17).
- Regulator notice: credit unions answer item 8 of NCUA's Credit Union Profile form instructions when they plan a core application conversion in the next 24 months, naming the application type (general ledger, shares and loans, or other), the anticipated conversion date and the core application they will convert to.
Tip: Ask the current provider for a sample deconversion file in the first month. The file layout drives the whole mapping effort, and waiting for it is the most common early delay.
Phase 2: inventory everything connected to the core
The inventory lists every product on the core and every system that exchanges data with it. A missed connection is the failure that shows up on Monday morning, when a feed stops and nobody knows it existed.
- Products and account types: deposits, loans, lines of credit, certificates, and the fees, rates and statement cycles attached to each.
- Systems that read from the core: online and mobile banking, the data warehouse, regulatory and management reports, collections, marketing lists.
- Systems that write to the core: loan origination, card processing, ACH and wire, teller, account opening and KYC tools.
- File feeds and scheduled jobs: nightly extracts, files on network shares and SFTP servers, jobs that run SQL against the core's database, and their schedules.
- The general ledger: how the core posts to the GL, at what level of detail, and who reconciles it.
Phase 3: data profiling and mapping
Data profiling and mapping turn the old core's records into the new core's structure, field by field, with a written rule for each transformation.
- Profile the source data before mapping: empty required fields, invalid dates, duplicate customers, accounts without an owner, codes that mean different things in different products.
- Watch older formats: data from legacy platforms can use EBCDIC encoding, packed decimal numbers and non-standard date formats. A conversion that misreads them produces values that look valid and are wrong.
- Map every field to the new core, with the rule, the default when the source is empty, and who approved it.
- Keep the rules versioned in one place, so a change after a mock conversion is visible and repeatable.
- Map compliance data explicitly: customer risk ratings, CIP verification status, beneficial ownership records, and BSA codes. These rarely affect a balance, so errors in them survive balancing.
Note: The legacy code does not have to be rewritten to be left behind. The old core only has to produce clean extracts; the transformation and validation happen between the extract and the new core.
Phase 4: validate in five layers before cutover
Validation before cutover means checking every migrated record in five layers, because a record count alone cannot show that values are right.
Run all five layers on every mock conversion, not just the last one, and record the results. A difference found in the first mock is a mapping fix; the same difference found on cutover weekend is a go or no-go decision.
Note: The CIP rule, 31 CFR 1020.220, requires banks to keep identifying information for five years after the account is closed, and verification records for five years after the record is made. Make sure records for closed accounts are kept somewhere you can retrieve them, even if they do not move to the new core.
Phase 5: rehearse the conversion
Rehearsals prove that the conversion can be done in the time you have, with results you trust.
- Run at least two full mock conversions on production-sized data, with all five validation layers each time.
- Write a cutover runbook with every step, its owner, its start time and its expected duration, and time it during the mocks.
- Test the integrations against the new core in its test environment: each feed, each file and each write from the inventory.
- Set go or no-go criteria in advance: which differences block go-live, which can be fixed afterwards, and who decides.
- Define rollback: the point after which you cannot go back to the old core, and what you do before that point if a check fails.
Phase 6: cutover weekend and the first weeks
Cutover is the final extract, conversion, validation and switch, done in the order the runbook sets.
- Freeze changes to products, rates and fees on the old core before the final extract.
- Take the final extract at close of business and record the source control totals.
- Convert and validate in all five layers, and balance totals by product and to the GL.
- Move the integrations to the new core in the order the inventory sets, and confirm each with its owner.
- Decide go or no-go against the criteria agreed in advance.
- Monitor the first weeks: daily balancing between the new core and the GL, failed feeds, customer complaints, and open differences with an owner and a due date.
Where engini fits in a core migration
engini fits around the conversion, not inside it. It connects to both the old and the new core, the systems around them, and the files they exchange, so the checks and the integration moves in this checklist can run as workflows with a record of each run.
- Both cores' data. engini connects to MS SQL, Oracle, IBM DB2, MySQL, Postgres and Snowflake. It can run a stored procedure your team already uses or your own SQL statement, for example the balancing queries from Phase 4, against the old core and the new one.
- Behind the firewall. The on-prem agent runs on your own server and opens every connection itself, outbound over HTTPS on port 443, so you open no inbound ports. It reaches on-premises databases, file drops in local folders and network shares, and internal REST applications.
- File feeds. Workflows read and write files on SFTP and FTP servers and in local folders, so a nightly feed can be checked during the parallel period and moved after cutover.
- Differences with an owner. Each difference from a balancing check becomes a record in an engini Table, and a table automation can notify its owner in Slack or Teams.
- Moving integrations. Each connection to a system is defined once. Through the API, the replace connection endpoint repoints a workflow from one connection to another and leaves the original intact, so each integration can be moved, tested and moved back if needed.
- Environments. Workspaces have separate development, staging and production environments, so integrations can be tested against the new core's test system first.
- A record of every run. Run history lists each execution by status and date, every run is recorded under the user who triggered it, and the audit log can be exported and streamed to your SIEM.
When you do not need engini: if your new core provider's conversion team handles mapping and balancing, and few systems connect to your core, their tools and your team may be enough. engini fits when many systems, file feeds and on-premises databases connect to the core and each has to be checked and moved. For related reading, see a bank merger data migration, core system cutover with AI agents, data migration in banking core modernization, and engini for financial services.
Frequently Asked Questions
What is a core migration checklist for banks and credit unions?
It is the list of decisions and checks needed to move an institution from one core banking system to another: contracts, inventory, data mapping, validation, rehearsals and cutover. Each item has an owner and a due date.
How do banks validate data integrity after migrating to a new core?
They validate in layers: structure, referential integrity, business rules, financial balancing to source totals and the GL, and completeness of compliance records. The checks run on every mock conversion and again at cutover.
Do credit unions have to tell NCUA about a core conversion?
Credit unions report a planned core application conversion on the Credit Union Profile form when it is expected within the next 24 months. They give the application type, the anticipated date and the new core application.
Can a bank migrate its core without rewriting legacy code?
Yes, a migration moves data, not code. The old core only has to produce reliable extracts; mapping, transformation and validation happen outside it, and the legacy code is retired after cutover.
How many mock conversions should a bank run?
Run at least two full mock conversions on production-sized data, validating all five layers each time. More are needed if the first ones show mapping or balancing differences.
Sources
- NCUA: Credit Union Profile Form 4501A instructions, effective December 31, 2024
- Federal Reserve: Interagency guidance on third-party relationships (June 6, 2023)
- OCC Bulletin 2023-17: Third-Party Relationships, Interagency Guidance on Risk Management
- 31 CFR 1020.220: Customer identification program requirements for banks
- engini docs: On Prem Agent, IBM DB2, SFTP, Replace connection
- engini docs index for AI agents